
Financial organizations generate more structured, high-value data than almost any other industry, transaction records, market feeds, credit histories, and portfolio positions, yet much of it still drives decisions through spreadsheets and quarterly reports rather than models built to catch risk in real time. Data science for finance is the discipline of turning that data into predictive models, risk scores, and forecasts that hold up under regulatory review and produce measurable financial outcomes. At DataScienceConsultingPro, we build these systems for banks, investment firms, hedge funds, asset managers, fintech companies, and insurers that need results a CFO, a chief risk officer, and a compliance team can all stand behind.
Why Financial Organizations Struggle to Use Their Own Data
Most banks, funds, and financial institutions don’t lack data. They lack the infrastructure, governance, and modeling discipline to use it at the speed the business actually needs. A handful of patterns show up in nearly every engagement we scope.
Data is fragmented across core systems. Core banking platforms, trading systems, CRM tools, and third-party market data feeds each hold a different piece of the picture. A credit risk model built only on internal repayment history misses the market and behavioral signals that often explain default risk earlier. Many institutions we work with are also weighing broader architecture questions at the same time, including whether a data mesh or data fabric approach fits their environment.
Regulatory requirements slow down experimentation. Model risk management frameworks, fair lending rules, and disclosure requirements mean a new model can’t simply be shipped and iterated the way it might be in a less regulated industry. That caution is appropriate, but it also leads many institutions to under-invest in analytics because the compliance burden feels heavier than the expected upside.
Legacy infrastructure limits what’s technically possible. Mainframe-era core systems, batch-only data pipelines, and vendor lock-in with legacy risk platforms make real-time or near-real-time analytics genuinely difficult to build without significant re-architecture. Institutions in this position often benefit from resolving foundational data quality management issues, and from clarity on ETL versus ELT approaches, before any predictive modeling work begins.
Internal teams are stretched thin. IT and quant teams inside financial institutions are typically staffed to keep trading, payments, and core banking systems running securely, not to build and maintain custom machine learning pipelines on top of them.
Analytics investments don’t always change what decision-makers actually do. Dashboards get built. Models get trained. Then adoption stalls because the output wasn’t designed around a specific underwriting, trading, or risk decision a business team actually owns. This is the single most common failure pattern we see, and it’s the one our methodology is built to prevent.
Our Data Science for Finance Services
Every engagement starts from a specific financial decision, not a technology stack. Below are the core services we deliver as part of data science for finance organizations.
Financial Data Strategy and Roadmapping
Before any model gets built, we assess data maturity: what data exists, where it lives, how clean and governed it is, and what decisions leadership actually needs support for. This often draws on our data governance consulting services and, where generative AI or automation is part of the roadmap, our AI strategy consulting work. The output is a prioritized roadmap, typically two to three initiatives sequenced by feasibility, regulatory complexity, and expected financial impact.
Predictive Risk and Credit Modeling
We build models for credit risk scoring, probability of default, loss given default, and early warning indicators for portfolio deterioration, drawing on our broader data modeling services where a project calls for it, and moving into a dedicated credit risk analytics engagement for lenders with an ongoing need. Every model we deliver includes documentation on its intended use, validation methodology, and known limitations, because an undocumented risk model is a liability during any regulatory exam.
Fraud and Anomaly Detection Model Development
We design statistical and machine learning models that flag suspicious transactions, account behavior, and application patterns for review, built to reduce false positives without missing genuine fraud signals. For institutions further along this path, this work often connects to a dedicated fraud detection AI program and to AI workflow automation services that route flagged cases to the right reviewer automatically. These models are scoped with compliance and fraud operations teams from day one, since a model that floods analysts with false alerts gets ignored regardless of its underlying accuracy.
Financial Data Engineering and Integration
Combining core banking data, market data feeds, and third-party data sources requires more than a data warehouse. It requires pipelines that respect regulatory data lineage requirements while making data usable for downstream analytics. Depending on where your infrastructure stands today, this work draws on our data engineering services, data pipeline development services, and, for institutions consolidating systems after a merger or core banking migration, our data migration services. We build with practices that keep pipelines maintainable long after our engagement ends.
Portfolio and Investment Analytics
For asset managers, hedge funds, and private equity firms, we build performance attribution models, factor exposure analysis, and scenario testing frameworks that support both investment decisions and investor reporting. Quant teams building this out internally sometimes start with our overview of data analysis methods used in quantitative research. This is typically supported by our statistical analysis services and data visualization services, and firms with a broader mandate sometimes extend this into a dedicated investment analytics consulting engagement.
Financial Forecasting and Scenario Modeling
We develop revenue forecasting, cash flow projection, and stress testing models designed to support planning cycles, board reporting, and regulatory scenario analysis requirements such as CCAR and DFAST style stress tests. Smaller, forecasting-specific requests are often handled through our data analysis services, while treasury and planning teams with recurring needs typically move into a standing financial forecasting consulting arrangement.
Financial Operations and Process Analytics
Not every problem is risk or investment related. Loan processing time, claims processing efficiency, and customer churn analytics are often where the fastest measurable return shows up, because the underlying data is cleaner and the decisions sit more directly within the organization’s control. High transaction volumes here are usually where our big data analytics services come in, and our piece on using data to improve customer experience covers some of the same thinking behind our churn analytics approach.
A number of these services are also delivered as standalone engagements in their own right rather than only as part of a larger data science project, so it’s worth exploring them directly if a narrower need is what brought you here.
Our Technology Stack for Financial Data Science
We select tools based on your existing infrastructure, regulatory environment, and internal team capabilities rather than defaulting to a fixed stack. Common components include:
- Data standards and connectivity: FIX protocol for trading data, SWIFT messaging for payments, standard core banking APIs, and third-party market data integrations (Bloomberg, Refinitiv, and comparable providers)
- Data platforms: Cloud environments configured for financial services compliance requirements (AWS, Azure, or GCP, depending on existing vendor relationships), on-premise or hybrid options where policy requires it, often set up in partnership with our cloud engineering services team
- Data engineering: SQL-based pipelines, Python (pandas, Apache Airflow), dbt for transformation workflows, and streaming infrastructure (Kafka or comparable) for real-time fraud and trading use cases
- Modeling and statistics: Python and R for statistical and machine learning models (our machine learning consulting service covers custom pipeline work in more depth, and our Python for data analysis piece is a useful primer if your team is newer to the language), scikit-learn and gradient-boosted tree libraries for classification and risk scoring, time series methods for forecasting and volatility modeling
- Visualization and reporting: Power BI, Tableau, or custom dashboards depending on how outputs need to be consumed by risk committees, investment teams, or regulators. Teams building out this layer on their own sometimes start with our articles on Power BI versus Excel or how to create a dashboard in Power BI, and larger reporting programs are often handled through dedicated business intelligence, Power BI, or Tableau consulting engagements
- Security and access control: Role-based access control, encryption at rest and in transit, and audit logging configured to support model risk management and regulatory examination requirements
We do not recommend a specific vendor stack until we understand what you already run. Migrating a bank off an existing, working core system rarely makes sense just to standardize on a preferred toolset.
Our Methodology
We follow a five-phase methodology on nearly every engagement, adjusted for scope and starting data maturity.
Phase 1: Discovery and Data Assessment. We interview risk, trading, compliance, and IT stakeholders, inventory available data sources, and assess data quality and governance. This phase typically surfaces the specific regulatory requirements that will shape the rest of the engagement.
Phase 2: Data Integration and Cleaning. Financial data is rarely analysis-ready across systems. This phase involves reconciling identifiers across platforms, handling missing and inconsistent records, and building the pipelines that will feed downstream models, work that sits at the core of our data engineering practice. Teams weighing their underlying storage architecture at this stage often find our data warehouse versus database comparison useful background.
Phase 3: Feature Engineering and Modeling. We translate financial and risk domain knowledge into model features, then build and validate statistical or machine learning models against the specific outcome in question, whether that’s default risk, fraud likelihood, or forecast accuracy.
Phase 4: Validation and Model Risk Review. Every model is reviewed with relevant stakeholders before deployment, risk committees for credit and risk models, compliance for fraud and AML related models. We document performance, known limitations, and appropriate use boundaries in a format built to withstand internal model risk management review.
Phase 5: Deployment and Continuous Monitoring. Models are deployed into existing workflows where possible, with monitoring in place to catch performance drift as market conditions and customer behavior change. We build feedback loops so models are retrained on a defined schedule rather than degrading silently over time.

How Risk and Investment Decisions Get Supported, Not Replaced
A recurring concern from risk committees and investment leadership is that predictive models will be used to override human judgment on decisions that carry regulatory or fiduciary weight. Our framework is built explicitly to avoid that.
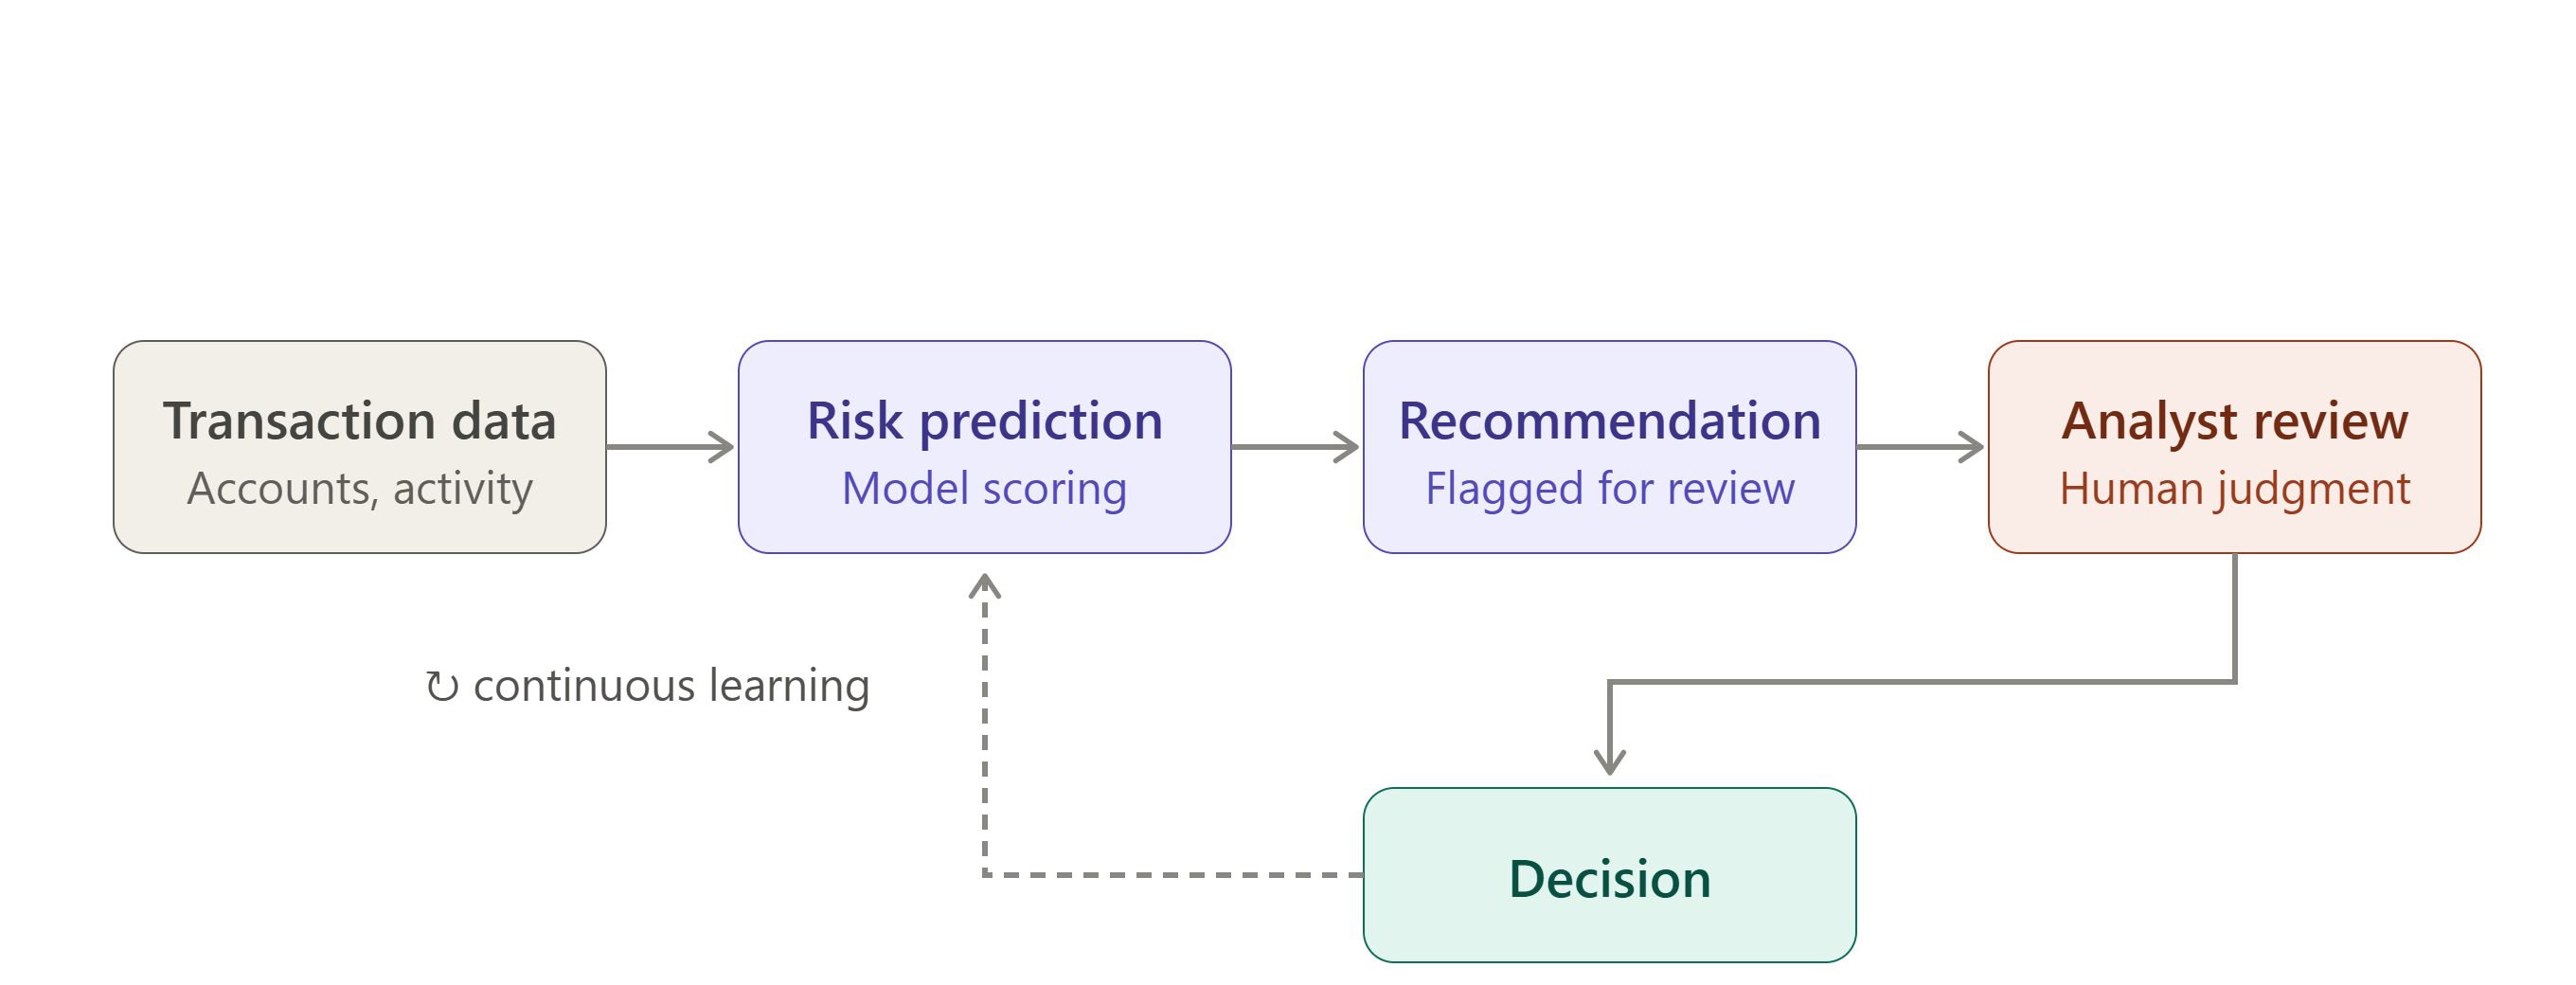
Every model we deploy in a risk, credit, or fraud context is positioned as a decision-support input, with a defined human review step before any account action, credit decision, or trade is finalized. This isn’t just good governance. It’s the position regulators, internal auditors, and model risk management frameworks expect to see, and it’s the position that gets adoption from risk and compliance teams in practice.
Benefits of Data Science for Finance Organizations
Organizations that invest in structured data science consulting typically see improvement across several dimensions, though the magnitude depends heavily on starting data maturity and the specific use cases pursued:
- Earlier identification of credit and portfolio risk through predictive models instead of lagging historical reporting
- Reduced fraud losses through models tuned to catch genuine fraud patterns while reducing false positive review volume
- Faster, more consistent underwriting decisions using models that supplement, rather than replace, underwriter judgment
- Improved forecasting accuracy for revenue, cash flow, and stress testing scenarios
- Stronger regulatory posture through documented, auditable model development rather than ad hoc spreadsheet analysis
- Better-informed capital allocation and investment decisions through portfolio and factor exposure analytics
Industry Applications
Banks. Credit risk scoring, early warning systems for portfolio deterioration, fraud detection, and customer churn analytics across retail and commercial banking segments, often as part of a broader banking analytics relationship for institutions with multiple lines of business.
Investment Firms and Hedge Funds. Factor analysis, alternative data integration, signal research support, and risk exposure monitoring across portfolios and strategies.
Asset Managers. Performance attribution modeling, portfolio construction analytics, and investor reporting infrastructure built to scale across multiple funds and mandates.
FinTech Companies. Data architecture built to scale from day one, credit and fraud models that support regulatory and partner bank due diligence, and analytics that support investor conversations as the company grows.
Credit Unions. Member risk and retention analytics, loan pricing models, and operational efficiency analytics scoped for smaller data teams and budgets.
Insurance Companies. Underwriting risk models, claims fraud detection, and policyholder retention analytics.
Mortgage Companies. Default risk modeling, prepayment risk analytics, and loan origination process efficiency analytics, frequently paired with financial dashboard development so origination and servicing teams can track these metrics day to day.
Venture Capital and Private Equity Firms. Portfolio company performance benchmarking, deal sourcing analytics, and due diligence data analysis frameworks.
Financial Advisors and Wealth Management Firms. Client segmentation analytics, churn and retention modeling, and portfolio risk analytics that support advisor recommendations.
Compliance, Security, and Regulatory Alignment
Data science work in finance has to be built around regulatory requirements from the start, not retrofitted after a model works. For risk functions with requirements that go beyond a single model, this is often the entry point into our broader risk analytics work, and institutions exploring generative AI use cases alongside their risk program typically loop in our AI consulting team as well. Our approach is informed by:
- SEC and FINRA considerations for any analytics work touching investment recommendations, trading, or investor disclosures
- Model risk management frameworks (informed by guidance such as SR 11-7 in the United States) for documentation, validation, and ongoing monitoring of predictive models
- Fair lending and anti-discrimination requirements for any model influencing credit or underwriting decisions, including testing for disparate impact across protected groups
- Anti-Money Laundering (AML) and Know Your Customer (KYC) requirements for transaction monitoring and fraud detection systems
- Basel III capital and risk reporting considerations for banking institutions
- SOX controls for any analytics feeding financial reporting processes
- GDPR and comparable data privacy regulations where engagements involve customer data across jurisdictions
- ISO 27001 information security management principles, applied to how data pipelines and model infrastructure are built and monitored
We do not position ourselves as legal counsel, auditors, or a compliance certification body. Every engagement involving sensitive financial or customer data includes a data governance conversation with your compliance, legal, and model risk teams before implementation begins, and we recommend independent regulatory review for any model that will influence credit, trading, or disclosure decisions.
Business Value of Financial Data Science Investment
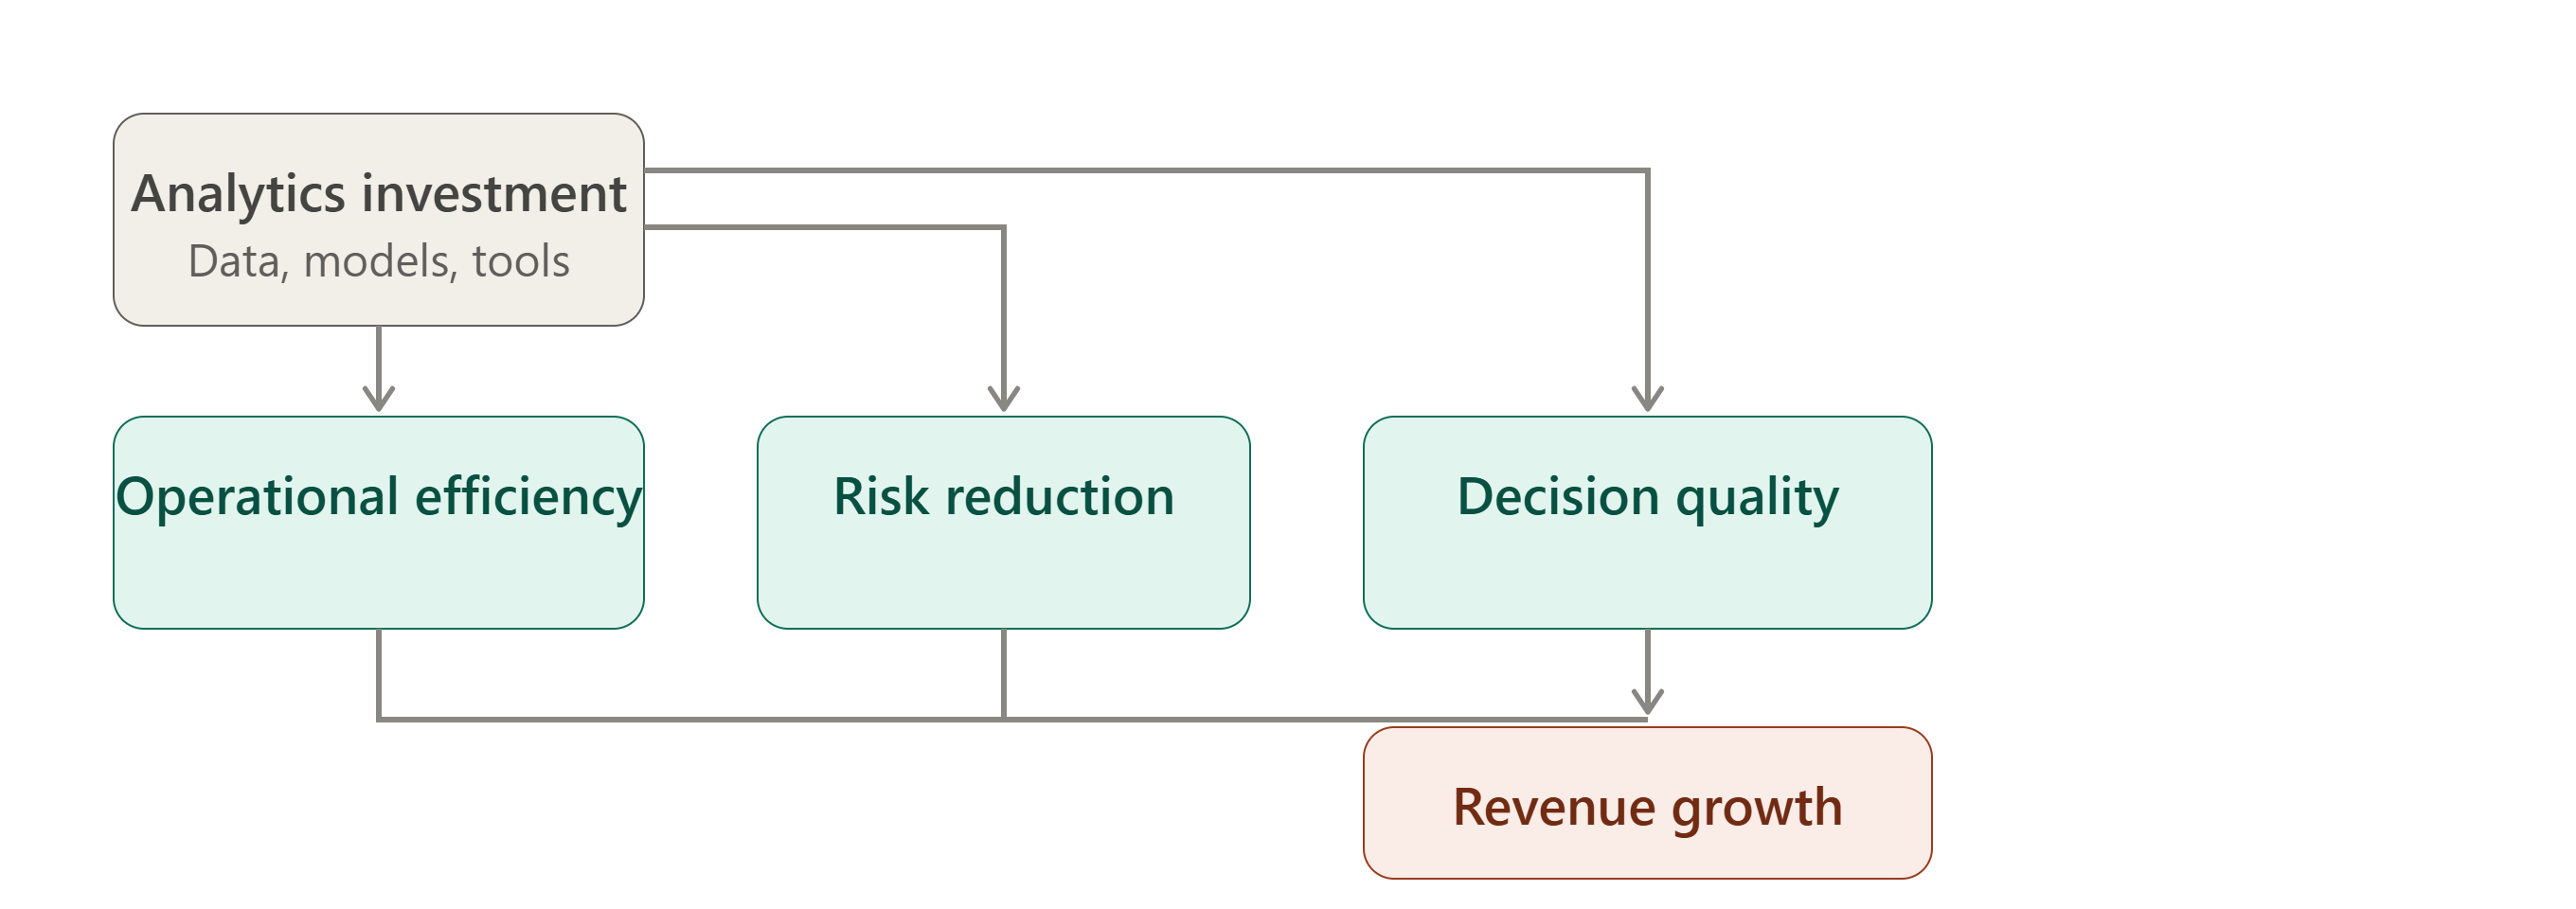
The business case for data science in finance rests on a simple sequence: better data leads to better models, better models improve the speed and accuracy of risk, credit, and investment decisions, and organizations that consistently make better decisions than competitors build a durable advantage, whether that’s a bank winning share on better underwriting speed or a fund demonstrating a data-driven edge to investors.
Pricing
Final pricing depends on project scope, data volume, number of source systems requiring integration, regulatory requirements, existing infrastructure complexity, and implementation timeline. The ranges below are starting points for planning purposes.
| Package | Suitable For | Estimated Price |
|---|---|---|
| Starter | Credit unions, small lenders, and fintech startups | $2,000 to $6,000 |
| Professional | Banks, insurers, and mid-size asset managers | $6,000 to $25,000 |
| Enterprise | Multi-entity banks, hedge funds, and global institutions | Custom Quote |
Every proposal includes a detailed scope document before work begins, so there are no surprise costs once an engagement is underway. If your organization has an unusual environment (multiple legacy core systems, cross-border regulatory requirements, or a highly regulated trading context), expect a custom scoping conversation rather than a fixed package. If you’d like a tailored estimate before that conversation, you can request a quote and we’ll follow up with next steps.
Illustrative Case Study: Credit Risk Model Modernization
The following is a representative example of a typical engagement structure. Specific client details are illustrative and should be replaced with a verified, permissioned case study before publication.
A regional bank engaged our team to modernize a credit risk scoring model that relied primarily on traditional bureau data and had not been retrained in several years. Underwriting decisions were increasingly inconsistent with actual portfolio performance, and the model lacked documentation sufficient to satisfy an upcoming regulatory exam.
Over a 16 week engagement, we integrated internal repayment history with updated bureau data and selected alternative data sources, rebuilt the risk model using a validated, explainable modeling approach, and delivered full model documentation covering methodology, validation results, and fair lending testing. Risk committee stakeholders reviewed model logic and limitations before go-live, and an underwriter review step was preserved in the workflow for any application flagged as borderline.
The engagement concluded with a documented model validation report, a monitoring plan to track model performance against real-world repayment outcomes, and a training session for the underwriting team. (Specific outcome metrics should be added only once verified against the client’s own reporting and reviewed for accuracy before this page is published.)
What to Look For When Choosing a Financial Data Science Partner
Hiring a data science consultant for a financial institution is a different decision than hiring one for a retail or logistics company, because the cost of a mistake is higher and the regulatory environment is less forgiving. A few questions worth asking any firm you’re evaluating, including us:
Have they actually built models that passed a real model risk management review, or only academic or portfolio projects? There’s a meaningful difference between a model that performs well in a notebook and one that has been through a documented validation process a regulator would accept.
Can they explain their validation approach in plain language? If a vendor can’t clearly explain how a model was validated, what its known limitations are, and who reviewed it from a risk and compliance perspective, that’s a warning sign, not a detail to skip over because the technical answer sounds impressive.
Do they understand the difference between a model that’s statistically strong and one that’s operationally usable? A fraud model with excellent accuracy metrics is worthless if it generates so many false positives that analysts start ignoring its alerts. Ask how outputs get delivered into actual workflows, not just how accurate the underlying math is.
Will they put compliance responsibilities in writing? Clear data handling policies, defined model documentation standards, and a documented escalation process for security incidents should be non-negotiable, not upsells.
Do they scope engagements around your data reality, or a fixed methodology? Financial data environments vary enormously. A single-branch credit union and a multi-entity global bank need fundamentally different approaches. Be cautious of any firm proposing the same fixed-price package regardless of your infrastructure.
Can they show you how a past model’s performance was monitored after deployment? Models degrade as market conditions and customer behavior change. A consultant who talks only about the build phase and has no plan for post-deployment monitoring is setting you up for a model that quietly stops working within a year.
We’d rather you ask us these questions directly on a discovery call than take marketing copy at face value, including ours.
Common Mistakes Financial Organizations Make With Data Science Initiatives
A few patterns show up often enough in engagements that started as “fix what a previous vendor built” that they’re worth naming directly. Several of these connect to a point we’ve made more broadly in why AI strategy matters more in 2026: tools and models rarely fail on their own, planning around them does.
Building the model before defining the decision it supports. Teams sometimes start with “let’s predict default risk” without first agreeing on what action an underwriter or risk officer will take differently once they have that prediction. The result is a technically sound model nobody changes their workflow around.
Skipping model risk validation to hit a deadline. Pressure to show results quickly sometimes leads to deploying a model without adequate review from risk and compliance stakeholders. This is where trust gets lost. Once a risk committee catches a model making an unexplainable or biased recommendation, it becomes difficult to win back confidence in anything the model says afterward.
Treating regulatory requirements as a final checkbox instead of a design constraint. Retrofitting fair lending testing or model documentation onto a pipeline that was built without them in mind is slower and riskier than designing around those constraints from day one.
Underestimating the data cleaning effort. In nearly every engagement, data integration and cleaning take longer than initial estimates suggest, particularly when reconciling customer and account identifiers across systems that were never designed to talk to each other. Budgeting realistic time for this phase avoids downstream schedule pressure that leads to shortcuts elsewhere.
Choosing tools before choosing the question. Institutions sometimes purchase a BI platform or analytics tool first, then look for a use case to justify the investment. Starting from the financial or risk question and choosing tools afterward produces better outcomes and avoids paying for capability you don’t need.
Frequently Asked Questions
It typically includes a data assessment, integration and cleaning of relevant data sources, model development for a specific risk, fraud, or forecasting question, validation with your stakeholders, and deployment support. The exact scope depends on your starting data maturity and the business question being addressed.
Traditional financial analytics often relies on historical reporting and static models built in spreadsheets. Data science for finance builds statistical and machine learning models designed to predict outcomes, such as default risk or fraud likelihood, rather than just describe what already happened.
We build pipelines and models around documented validation, fair lending testing where relevant, and data governance best practices, and we recommend a compliance and model risk conversation with your internal teams before any sensitive data is touched. We are not a substitute for your organization’s own compliance and legal review.
No. Every model we build for credit, risk, or fraud use is designed as a decision-support input with a human review step before final decisions are made.
Smaller, focused engagements can run 8 to 12 weeks. Larger, multi-source integration projects for banks or asset managers often run 4 to 8 months, sometimes longer depending on regulatory review requirements.
Yes, model performance can drift as market conditions and customer behavior change over time. We recommend a monitoring plan and can provide ongoing support to track and retrain models as needed.
Yes, including transaction monitoring, application fraud detection, account takeover risk models, and the underlying anomaly detection infrastructure that supports AML programs, typically integrated with existing fraud and compliance workflows.
Yes, most engagements are structured as augmentation of existing teams, with knowledge transfer built into the final phase so your internal team can maintain and extend the work after we’re gone.
Data quality assessment is part of Phase 1 of our methodology. Poor data quality doesn’t disqualify an engagement, but it does affect scope and timeline, since data cleaning often becomes a larger share of the project.
A real risk if models are trained on unrepresentative data or proxy variables correlated with protected characteristics. We test for performance disparities across relevant customer subgroups as part of validation and document any identified limitations before deployment.
Yes, during discovery, we’ll tell you honestly if your need is better served by a business intelligence or reporting engagement rather than a full predictive modeling project. Not every problem requires machine learning.
Any engagement involving sensitive financial or customer data requires a signed NDA and appropriate data processing terms before data access begins. This is standard practice and something our team will raise during contracting, not something you need to request separately.
Multi-jurisdiction engagements require additional scoping for varying regulatory requirements. This is addressed during the discovery phase and typically moves an engagement into Enterprise-level scope.
Schedule a discovery call. We’ll discuss your current data environment, the financial or risk question you’re trying to answer, and whether a Starter, Professional, or Enterprise-level engagement fits your needs.
Ready to Turn Your Financial Data Into Better Decisions?
Data science for finance only creates value when it’s built around a real risk, credit, fraud, or investment question, validated with the people who will act on it, and deployed with regulatory requirements built in from day one, not bolted on afterward.
If your organization is ready to move past static reporting and toward predictive, decision-ready analytics, schedule a discovery call with our team. We’ll discuss your current data environment, the specific outcomes you’re trying to improve, and whether a Starter, Professional, or Enterprise engagement is the right fit, with no pressure and no generic sales pitch.
Explore our interactive revenue forecasting dashboard to see how finance teams can turn historical performance into practical forecasts.